Veo 3.1 Preview Shutdown: Before You Move to Gemini Omni
Veo 3.1 preview models in the Gemini API are due to end on October 22, 2026. Affected models, Gemini Omni specs and pricing, and our side-by-side test.
If you use a Veo 3.1 preview model in the Gemini API (a model name ending in -preview), it is scheduled to shut down on October 22, 2026. Google names Gemini Omni 1.1 Flash (gemini-omni-1.1-flash) as the replacement. The generally available veo-3.1-generate-001 on Vertex AI is listed for retirement "no earlier than November 17, 2026" and is not part of the October 22 shutdown.
This article covers the list of models being shut down as confirmed on official pages on October 14, 2026, how to tell which Veo you are using, and Gemini Omni's specs and pricing. We also share what happened when we took the image and prompts FablessBridge used for a Veo 3.1 test on Vertex AI on October 12 and ran them unchanged through Gemini Omni on October 14.
Veo 3.1 models shutting down on October 22, 2026
- 01veo-3.1-generate-preview (released October 15, 2025): scheduled shutdown October 22, 2026
- 02veo-3.1-fast-generate-preview (released October 15, 2025): scheduled shutdown October 22, 2026
- 03veo-3.1-lite-generate-preview (released March 31, 2026): scheduled shutdown October 22, 2026
- 04gemini-omni-flash-preview (the Gemini Omni preview): scheduled shutdown October 22, 2026
The replacement for all four is gemini-omni-1.1-flash. Google's deprecations page says the dates in the table are the earliest possible shutdown dates, and that exact dates will be announced in advance. The date may be pushed back, but it is safer to prepare on the assumption that these models stop on October 22.
The generally available models on Vertex AI (veo-3.1-generate-001 and veo-3.1-fast-generate-001, released November 17, 2025) are listed for retirement "no earlier than November 17, 2026," and no specific date has been set yet.
How to tell if your Veo model is affected
Even for the same Veo 3.1, the shutdown schedule depends on where you call it from. Check these two things.
- 01Endpoint: generativelanguage.googleapis.com means the Gemini API, and aiplatform.googleapis.com means Vertex AI
- 02Model name: ending in -preview means a preview model, and ending in -001 means a generally available model
https://{LOCATION}-aiplatform.googleapis.com/v1/projects/{PROJECT}/locations/{LOCATION}/
publishers/google/models/veo-3.1-generate-001:predictLongRunningIf you use Veo 3.1 through another service such as fal or Runway, the impact depends on which model that service connects to. Check each service's announcements and pricing pages for how it will handle Veo 3.1 after October 22.
What Gemini Omni 1.1 Flash can do
Gemini Omni 1.1 Flash is a model for generating and editing video that became generally available on August 27, 2026. The main specs we could confirm in the official documentation are as follows.
- 01Input: text, images (including interpolation between a specified first and last frame), reference images of people or objects, and reference videos (up to 3 clips of 3 seconds or less)
- 02Length: a generated video can be extended by adding 3 to 10 seconds at a time, up to 40 seconds in total
- 03Resolution: 360p, 720p (default), 1080p and 4K. 1080p and 4K are produced by upscaling
- 04Aspect ratio: 16:9 landscape (default) and 9:16 portrait
- 05Audio: generated with the video by default, and its content can be steered in the prompt
- 06Watermark: every generated video carries an invisible digital watermark (SynthID)
- 07Regional restrictions: in the European Economic Area, Switzerland and the UK, uploaded videos cannot be edited or extended
The way you give instructions also changes. There is no negative prompt field, no system instructions and no temperature setting, so anything you want to avoid has to go in the prompt itself. Assume that prompts and settings you used with Veo 3.1 will not give the same results as they are, and test them again.
Pricing compared: Veo 3.1 and Gemini Omni
- Veo 3.1
- $0.40 per second (720p and 1080p, with audio)
- Veo 3.1 Fast
- $0.10 per second (720p, with audio)
- Veo 3.1 Lite
- $0.05 per second (720p, with audio)
- Gemini Omni 1.1 Flash
- About $0.10 per second (720p)
All figures are from the Gemini API pricing page (as of October 14, 2026, excl. tax). Gemini Omni costs $17.50 per 1 million output tokens, with one second of 720p video counted as 5,792 tokens. For an 8-second 720p video, Veo 3.1 costs $3.20 and Gemini Omni about $0.80.
The pricing page did not say what Gemini Omni costs at resolutions other than 720p. If you plan to use 1080p or 4K, test with a small number of videos to confirm the actual cost.
Sources
Our earlier test with Veo 3.1
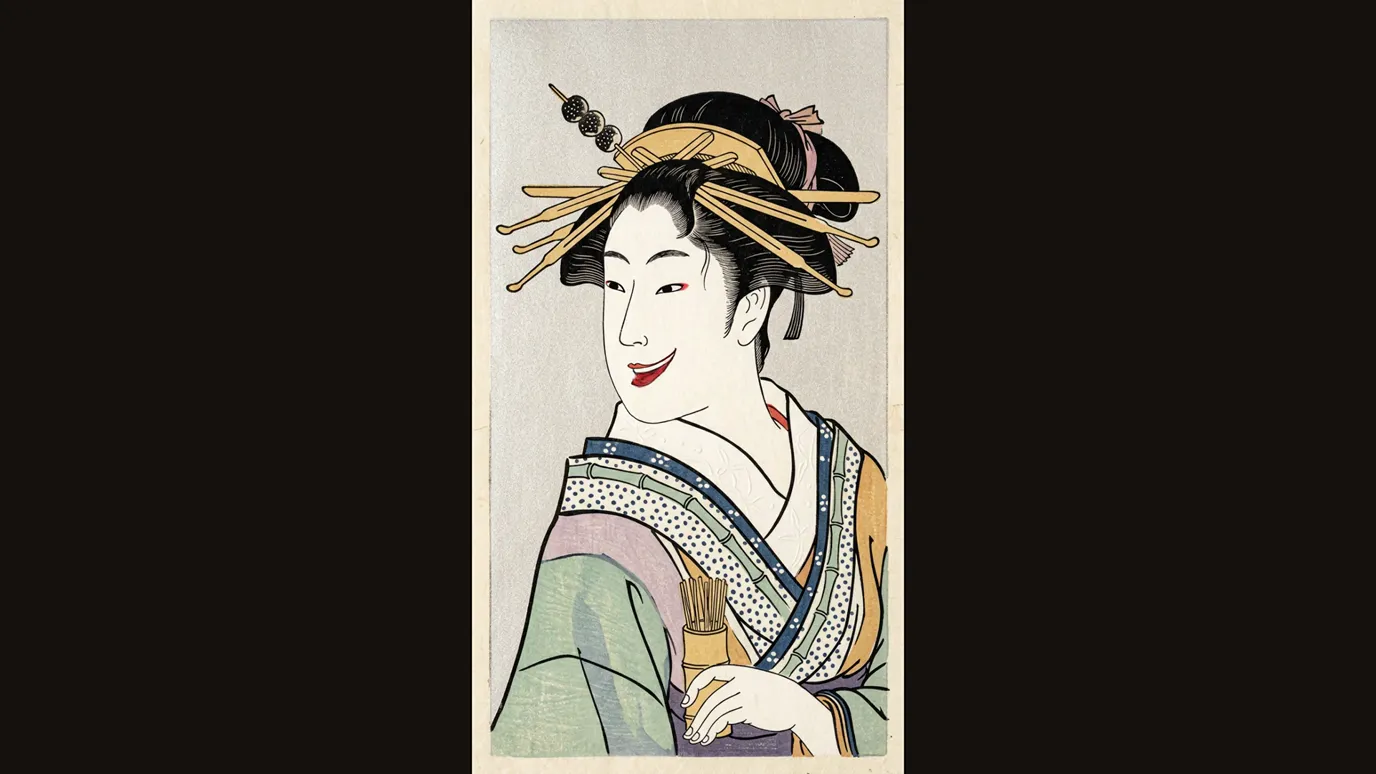
On October 12, we animated a single ukiyo-e style portrait of a woman with Veo 3.1 on Vertex AI (veo-3.1-generate-001). We ran it twice, in 9:16 portrait, 8 seconds, at 720p.
For the first run, we turned audio generation on and asked her to speak three lines of Japanese like a street vendor in Edo-period Tokyo. The flat colors and outlines typical of a woodblock print held up to the end, and her mouth moved with the lines. However, her head swung widely from side to side, and the shape of the hairpin changed from frame to frame. When we transcribed the generated audio with speech recognition, the second line came out almost as instructed, while parts of the first and third lines were transcribed differently.
For the second run, we turned audio generation off and instructed "do not move the head, move only the mouth and eyes." Even so, the direction of her face changed partway through, and in about the last second even her hand moved. In neither run did the model fully follow the instruction to hold still.
Results with Gemini Omni using the same image and prompts
On October 14, we gave the same portrait and the same prompts unchanged to Gemini Omni 1.1 Flash and made two videos in 9:16 portrait at 720p. There is no setting for duration: the run with dialogue came back at 10 seconds, and the mouth-and-eyes-only run, whose prompt included a timeline up to 8 seconds, came back at 8 seconds. Responses took about 42 and 36 seconds, and the costs, calculated from the output token counts in the responses, were about $1.03 and $0.83.
The biggest difference was how well the artwork held. In both Gemini Omni videos, the direction of the head and body barely changed and the hairpin kept its shape. In exchange, the mouth and eye movements were smaller. In both Veo 3.1 videos, the head moved a lot and the hairpin changed shape.
We also compared how clearly the lines could be understood. When we transcribed the audio of the three videos with the same speech recognition model (Whisper large-v3), Gemini Omni's three lines came out almost as instructed, the only difference being that "goma" (sesame) was transcribed as "kima." With Veo 3.1, the second line was nearly right, but the third was transcribed as a sentence that made no sense.
In the mouth-and-eyes-only run, Gemini Omni barely moved the head or hands and followed the instruction more closely than Veo 3.1. However, audio was added even though the prompt said "no audio." No lines could be made out, but there was sound. Gemini Omni has no setting we could find to turn audio off, so in productions where sound is made separately, we replace it in the edit.
Each test was a single video, so we cannot call these tendencies of the models. Still, for uses where you want to animate an image without breaking its art style, we found moving to Gemini Omni worth trying. If you want larger mouth movements, try again with differently written prompts.
What to check before moving to Gemini Omni
- 01Check from the endpoint and model name whether you are using a Gemini API preview model or a generally available Vertex AI model
- 02Try a few videos in Gemini Omni with the images and prompts you usually use
- 03Rewrite settings Gemini Omni does not support, such as negative prompts and temperature, into the prompt
- 04Audio is generated by default and is added even if you write "no audio," so if your production makes sound separately, decide how you will replace the audio in the edit
- 05There is no duration setting, so write a timeline in the prompt and check that the length comes out right
- 061080p and 4K are upscaled, so test to confirm the resolution you need and its cost
- 07If you produce for Europe or the UK, check whether the regional restrictions apply to you
Video generation AI models are replaced by newer ones every few months to a year. How to compare models, and how costs differ for the same model depending on the service you use, are covered in "How to choose a video generation AI."
Talk to us about your video
You don’t need a finished plan to get in touch.
ContactSee pricing and the production process